Perplexity Releases Lily Inference Engine for Apple Silicon
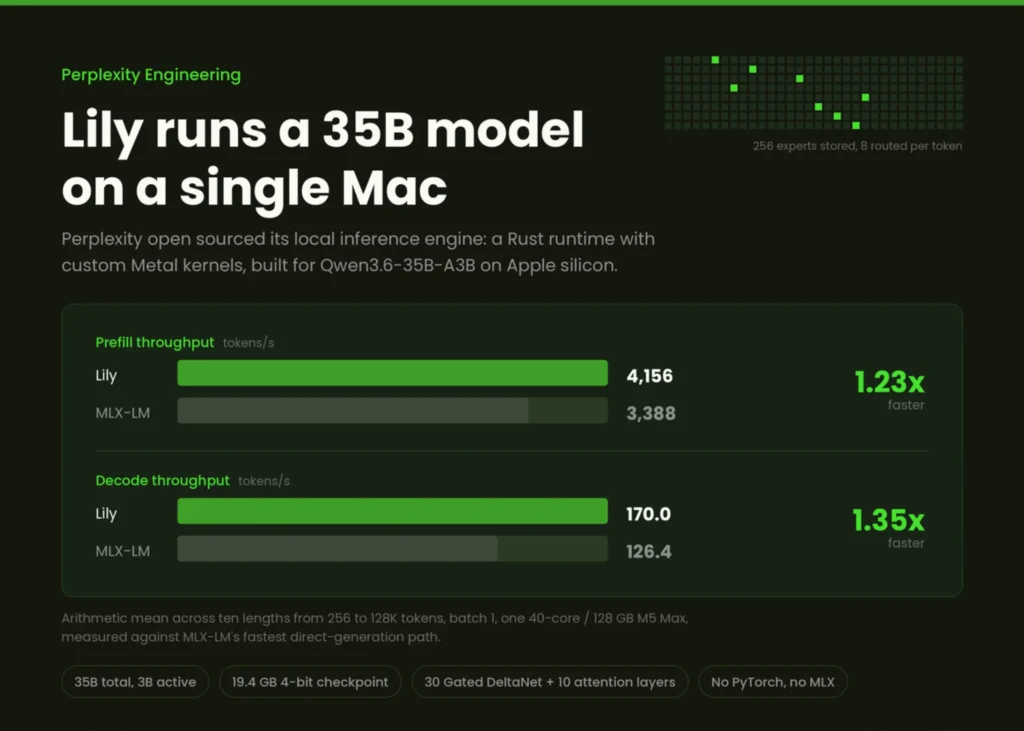
Perplexity has open-sourced Lily, a specialized inference engine built using Rust and Apple’s Metal framework, according to a report by MarkTechPost. Designed specifically for Apple Silicon hardware, Lily is engineered to run the Qwen3.6-35B-A3B model locally with high performance and low overhead.
By leveraging Rust for safety and performance alongside Metal for direct GPU acceleration on macOS devices, Lily provides builders and developers with a native tool for executing large language models locally on Apple hardware. The release targets the growing demand for efficient local inference solutions that bypass cloud infrastructure dependencies.
The open-source repository offers builders granular control over resource allocation and execution parameters on M-series chips. Detailed implementation steps and source code are available via Perplexity’s developer channels for teams looking to integrate local model serving into Apple-based development environments.
Based on reporting by www.marktechpost.com.