Redis Unveils LangCache for LLM API Cost Reduction
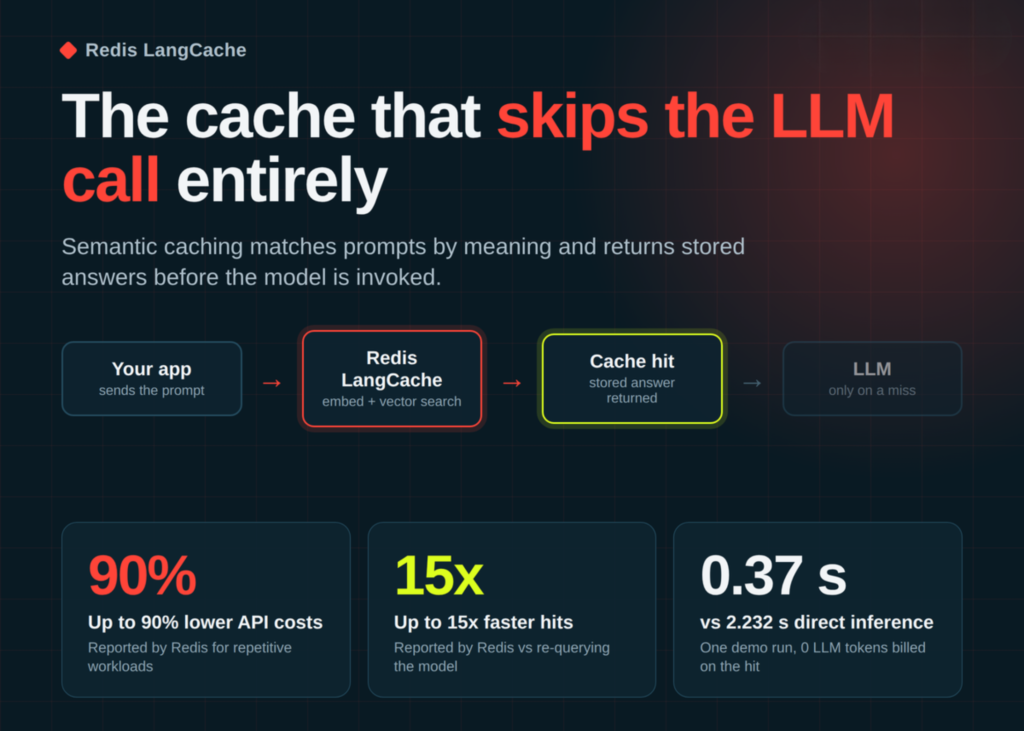
According to MarkTechPost, Redis has introduced LangCache, a managed semantic cache designed to lower large language model application expenses and accelerate retrieval times. The tool addresses rising infrastructure costs for engineering teams deploying generative AI features into production environments.
MarkTechPost reports that the managed semantic cache can reduce LLM API costs by up to ninety percent. Additionally, the system delivers cache hits up to fifteen times faster than standard query workflows by recognizing semantically similar user prompts and returning stored responses without hitting the underlying foundational model.
The release targets builders and enterprise developers struggling with latency and token expenditure at scale. By caching responses based on semantic meaning rather than exact string matching, LangCache aims to optimize resource allocation across heavy AI workloads while maintaining output relevance.
Based on reporting by www.marktechpost.com.