Controlling Model Behavior With Production AI Guardrails
As artificial intelligence systems transition from experimental environments to heavy production use cases, engineering teams face increasing challenges regarding output safety and model reliability. According to reporting by Unite.ai, implementing robust AI guardrails has become a core requirement for developers seeking to control model behavior in real time.
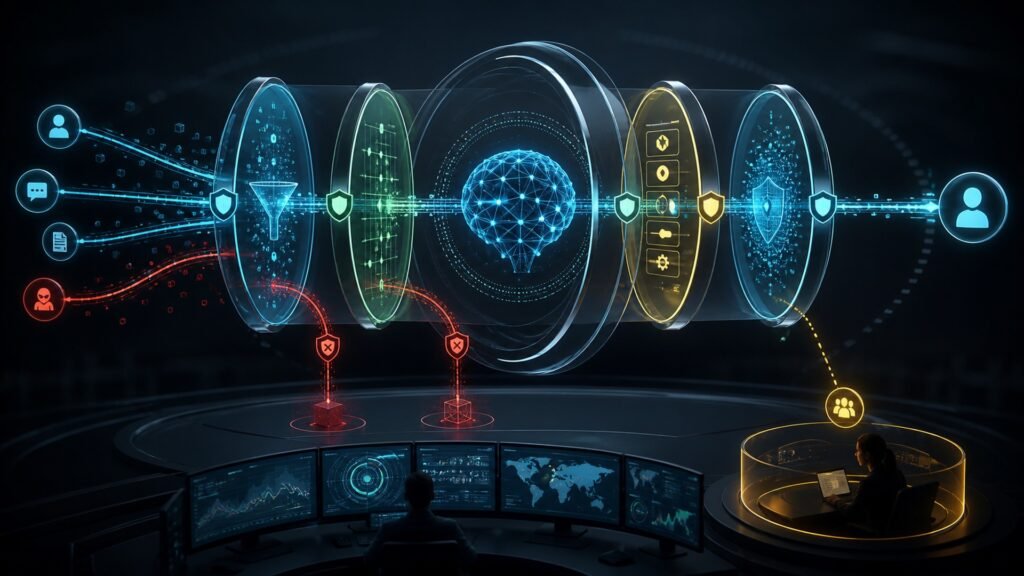
These mechanisms operate as defensive layers surrounding foundational models, filtering inputs for malicious prompts and scanning generated outputs for hallucinations, toxic language, or sensitive data leakage. For builders deploying large language models and autonomous agents, guardrails provide the deterministic oversight necessary to prevent unintended model actions. Without these systems in place, applications remain vulnerable to prompt injection attacks and erratic behavioral drift.
The integration of runtime guardrails typically involves a combination of heuristic checks, classification models, and policy enforcement engines positioned between the user interface and the core AI model. As regulatory compliance standards tighten and enterprise software requirements mature, developer tooling focused on model safety infrastructure continues to expand across the artificial intelligence ecosystem.
Based on reporting by www.unite.ai.