Liquid AI Releases LFM2.5-VL-3B-DSpark
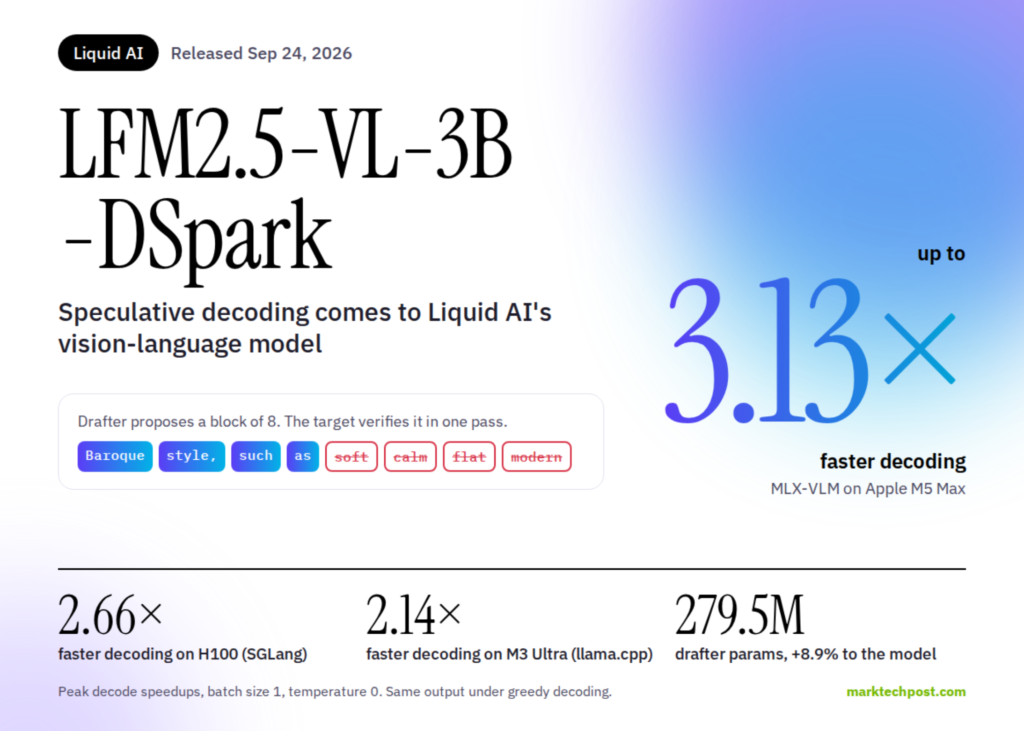
Liquid AI has officially announced the release of LFM2.5-VL-3B-DSpark, introducing advanced speculative decoding capabilities designed specifically for vision-language models. According to reporting by MarkTechPost, the new model architecture achieves up to 3.13 times faster decoding performance compared to standard baseline configurations.
For builders and developers working with multimodal systems, the integration of speculative decoding addresses key latency bottlenecks associated with processing both visual and textual tokens concurrently. By utilizing a smaller draft model to generate candidate tokens that are subsequently verified by the larger target model, LFM2.5-VL-3B-DSpark maintains output quality while drastically reducing inference times.
The release expands Liquid AI’s growing ecosystem of efficient foundational models tailored for resource-constrained environments and high-throughput production pipelines. The company states that the new architecture is optimized to handle complex visual reasoning tasks without sacrificing accuracy, offering a practical solution for real-time edge and cloud deployments.
Detailed technical specifications, benchmarks, and integration guidelines for LFM2.5-VL-3B-DSpark are available through Liquid AI’s official development channels and developer documentation platforms.
Based on reporting by www.marktechpost.com.