Nunchux AI Unveils VC-Attention for Video Models
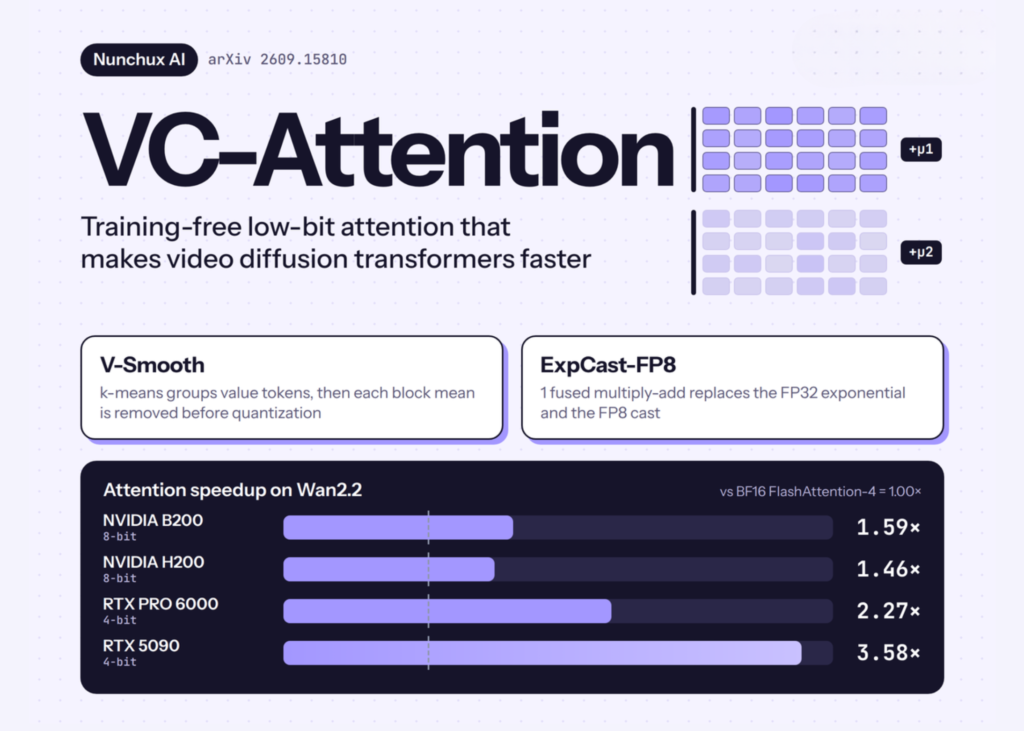
Nunchux AI has introduced VC-Attention, a training-free low-bit attention kernel designed to accelerate video diffusion transformers. According to MarkTechPost, the newly released kernel addresses computational bottlenecks common in video generation models by optimizing attention mechanisms without requiring extensive retraining phases.
Video diffusion transformers typically demand high computational overhead during inference due to the complexity of processing spatial and temporal dimensions simultaneously. The VC-Attention kernel operates by applying low-bit quantization strategies directly to the attention operations. This approach seeks to reduce memory bandwidth consumption and latency while preserving output fidelity.
Builders working with resource-intensive generative video architectures can integrate the attention kernel into existing pipelines without modifying base model weights or initiating costly fine-tuning cycles. The release targets deployment environments where hardware constraints and latency limitations restrict real-time or high-throughput video synthesis.
Further technical details regarding benchmark performance across standard video diffusion architectures are available through the Nunchux AI developer documentation and research disclosures.
Based on reporting by www.marktechpost.com.